Your Pilot Succeeded by Suppressing the Variance Your Rollout Has to Absorb
Why a smooth pilot tells you less about scaling than an awkward one — and the number you should have measured instead.
The pilot review goes well. OEE is up on the line you instrumented. Unplanned downtime is down. The plant manager is enthusiastic, the numbers survive finance’s questions, and the rollout is approved for twenty sites.
Eighteen months later, four are live. Two of those are running a forked version of the solution that no longer receives updates. The business case is quietly being rewritten, and somebody is preparing a slide about “change management challenges.”
This is usually described as a failure of execution. It is more often a failure of inference. The pilot answered a question nobody needed answered, and the answer was mistaken for one that mattered.
A pilot and a rollout ask different questions
A pilot asks: can this work here?
A rollout asks: can this work everywhere, at a cost that declines as we go?
Those are not the same question at different scales. They have different answers, and — this is the part that catches good teams — the first answer carries almost no information about the second.
Worse, the practices that produce a clean answer to the first question are frequently the same practices that guarantee a bad answer to the second.
The seven suppressions
Look closely at how a pilot actually gets delivered. Every decision below is rational in isolation. Every one is also a technique for removing variance.
1. You chose the site that said yes. Pilot sites are volunteers. Volunteers have cooperative management, spare engineering capacity, and usually newer equipment. You didn’t sample your network — you selected from it, on precisely the variables that make rollout hard.
2. You chose the best line within that site. The one with working sensors and current documentation. The lines where the tag list hasn’t matched reality since 2019 were not in scope.
3. Your engineers were physically present. Someone who understood the whole stack was standing on the floor when things broke. At site eleven, they will be on a call, three time zones away, describing a screen they cannot see.
4. Someone fixed the data by hand. There is always a spreadsheet. Master data was reconciled, categories were mapped, a few thousand rows were corrected by a person who knew what the values should have been. That work exists in no repository and appears in no plan.
5. Integration was written bespoke — because bespoke was fastest. Under time pressure, a specific adapter for a specific PLC on a specific line is the shortest path to a demo. It is also the path that produces zero reusable assets.
6. Change control was relaxed. Pilots get exceptions. Release windows bend, approvals compress, a senior sponsor clears obstacles personally. Site twelve will get the standard process and the standard queue.
7. The plant genuinely cared. It was a showcase. People made it work because visibility was on it. That motivation does not replicate across twenty sites, and it is the least transferable asset in the entire programme.
Each of these reduced variance so the technology could be evaluated cleanly. Together, they mean you evaluated the technology under conditions that will never occur again.
The corollary that stings
If those suppressions made the pilot succeed, then the smoother your pilot ran, the more variance was suppressed — and the less you learned.
A pilot that went perfectly may be telling you the technology works. It may equally be telling you that your team is very good at absorbing chaos on behalf of a system that cannot absorb it alone. Those two conclusions look identical in a steering committee deck, and only one survives contact with plant nine.
The most uncomfortable version: a pilot that succeeded because of heroics is evidence against scalability, not for it. Heroics do not deploy.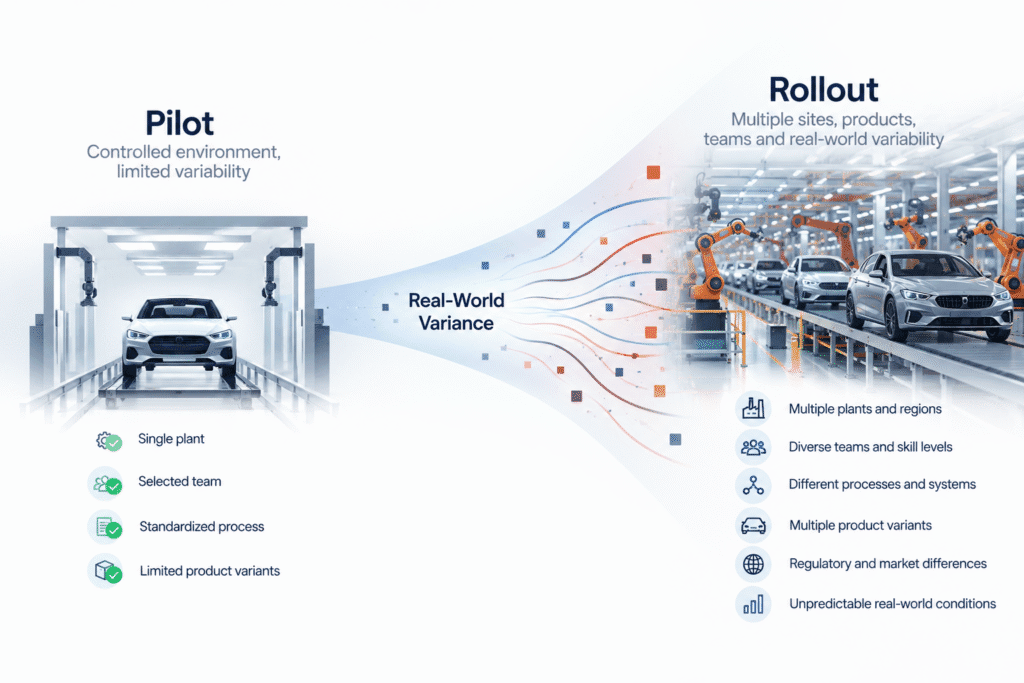
The accounting error nobody catches
Here is where the inference failure becomes a financial one.
In the pilot business case, integration and data-preparation effort is recorded as setup cost — a one-off, amortised across the value the solution will generate over time. That treatment is correct for software that installs identically everywhere.
It is wrong for bespoke integration. If the adapter, the field mappings and the data reconciliation were built specifically for that plant, then that cost is not one-off. It is cost per site, and it recurs in full at every plant in the network.
A business case built on the first interpretation and delivered under the second doesn’t miss by a few percent. It misses by a multiple, and the miss only becomes visible around site three — by which point the capital is committed and the programme is defending itself rather than correcting itself.
The number you should have measured
Software scales because the marginal cost of the next deployment approaches zero. Multi-plant manufacturing does not get that property for free. It has to be engineered in — and whether it has been is measurable.
The measure is simple: of everything site N requires — data model, connectivity configuration, integration code, validation logic, deployment tooling — what fraction is inherited unchanged from the template?
Call it the reuse ratio. It is the single variable that determines whether a rollout compounds or merely repeats, and almost no pilot business case reports it.
Now the trap, and it is a genuine one:
Building for high reuse makes site one more expensive. Templating, semantic standardisation and a proper asset model are overhead that delivers nothing to the first plant. A pilot judged on first-site ROI will therefore consistently prefer the bespoke approach — the one that looks cheaper, demonstrates faster, and quietly destroys the economics of every site that follows.
Your pilot governance may be actively selecting against scalability, and reporting it as efficiency.
Site two is the experiment
If site one is the demonstration, site two is where the rollout hypothesis actually gets tested. It is the first point at which reuse ratio can be measured rather than assumed: what transferred untouched, what needed reconfiguring, what had to be rebuilt.
Two conditions make that test worth running:
Pick a site that differs in a way that matters. A second plant with the same controller vendor, similar line vintage and comparable data maturity will produce an encouraging number that means nothing. Choose the awkward one — different equipment generation, different integration history, ideally one that arrived through an acquisition. You want the number that tells you the truth while it is still cheap to act on.
Decide in advance what result stops the programme. If effort at site two is not materially below site one, the template isn’t working. That finding is worth far more at site two than the same finding discovered at site eight, after the network budget has been spent learning it.
Three questions for your next pilot review
Before approving any rollout, ask:
Which artifacts from this pilot can be deployed at another site unchanged? Not “reused with modification” — unchanged. If nobody can answer precisely, the rollout cost is unknown.
What did we do by hand that we would have to do again? Every manual reconciliation, mapping and correction is a recurring cost currently recorded as a one-off.
If we ran this at our most awkward plant instead, what specifically would break? If the honest answer is “most of it,” the pilot proved feasibility and nothing else.
None of these requires new tooling or new budget. They require asking a different question at the review than the one the pilot was designed to answer.
The honest caveat
Not every scaling failure is this failure.
The published research on why transformation programmes stall points first and repeatedly to organisational causes — governance, ownership, decision rights, and whether plant leadership has any stake in an initiative delivered to them from the centre. Those causes are more common than the one described here, and no architecture compensates for their absence.
But this failure mode has a particular property that makes it worth isolating: it is systematically misdiagnosed. When a model underperforms at plant two, the investigation goes to the deployment, the configuration, sometimes the model. It rarely goes to the pilot design that made the result non-transferable in the first place — because the pilot, by every measure anyone recorded, went well.
Go deeper
This article covers the inference problem. The full whitepaper covers what to do about it:
- A worked cost model showing how reuse ratio changes a ten-site rollout — including exactly where the high-reuse path overtakes the bespoke one
- Three mechanisms that keep marginal cost per site high: semantic divergence, integration snowflakes, and model non-transferability
- A six-question diagnostic to establish which mechanisms are active in your network before committing rollout budget
- Six interventions with the trade-offs each carries — and a section on when not to do this at all
- What published multi-plant programmes actually report, including a network of ~140 plants that reached roughly 80% configuration reuse, and why that figure only arrived after deliberate blueprinting
A 20-page technical guide for manufacturing, operations and digital leaders. 16 cited sources.